The government publishes more than you can read
Using LLMs to keep track · Abigail Haddad
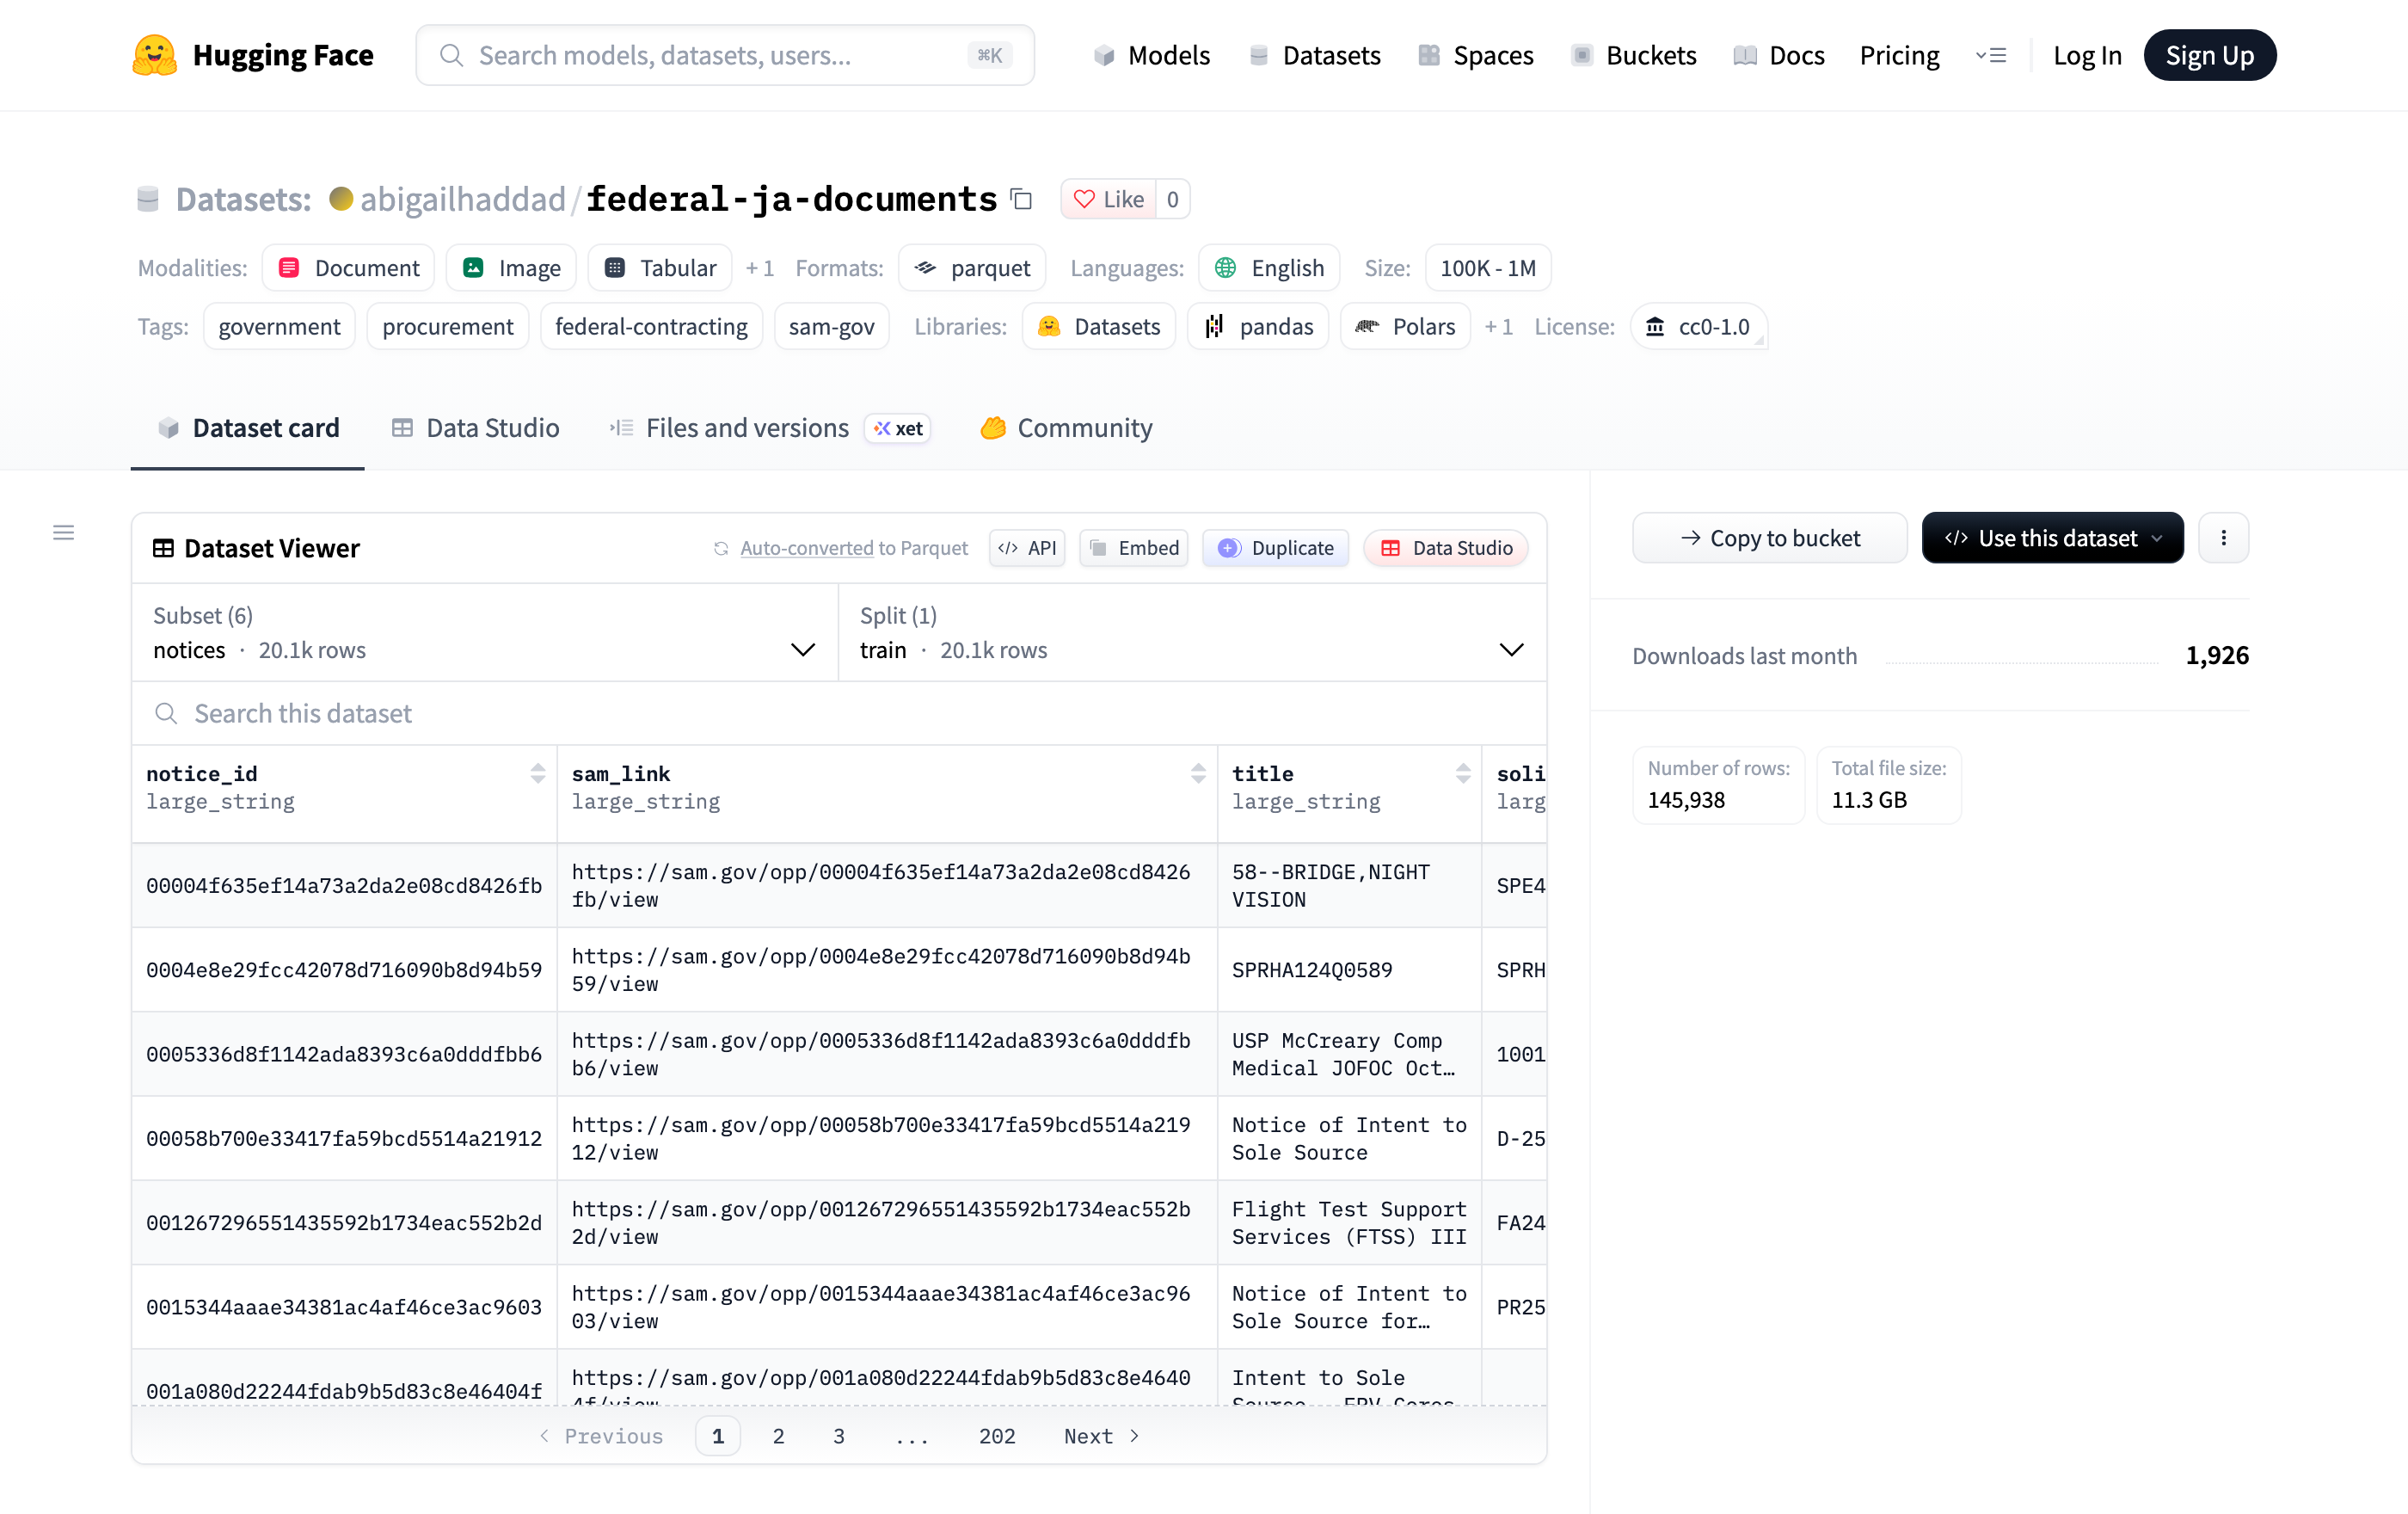
When an agency skips competition, it has to publish a document saying why.
I collect every one and put it on Hugging Face.
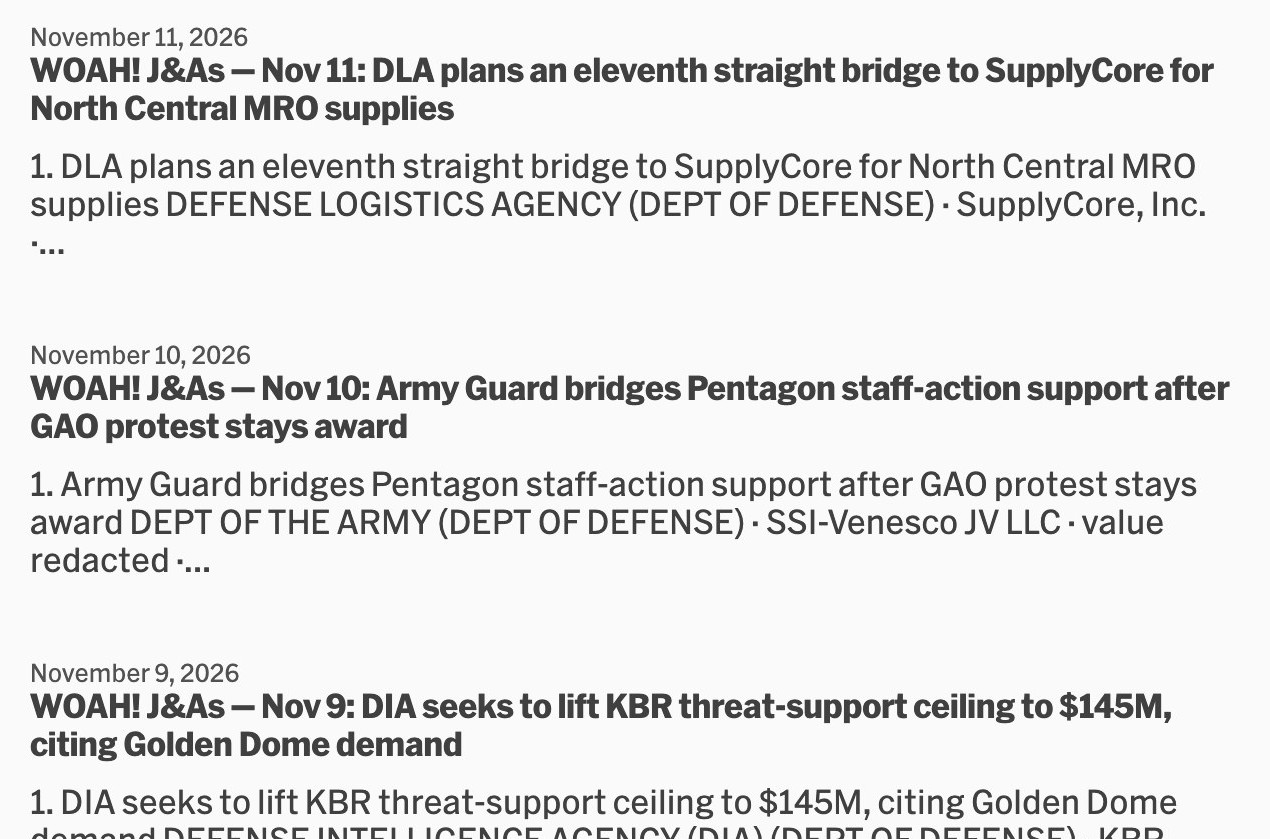
And I send a daily newsletter
Having this data set lets me ask questions
How often do workforce cuts or DOGE show up in sole-source justifications? 390 of 9,710. 41 name DOGE specifically.
Here are some other questions I wanted to answer
- What is OPM putting out this week?
- Who is commenting on a proposed reg, and are they for it?
- How often do federal IT jobs require a degree?
- How much was awarded this year citing “urgency”?
- Which vendors sell to the most DC agencies?
- How does ICE’s surge-hiring attrition compare to previous hiring efforts?
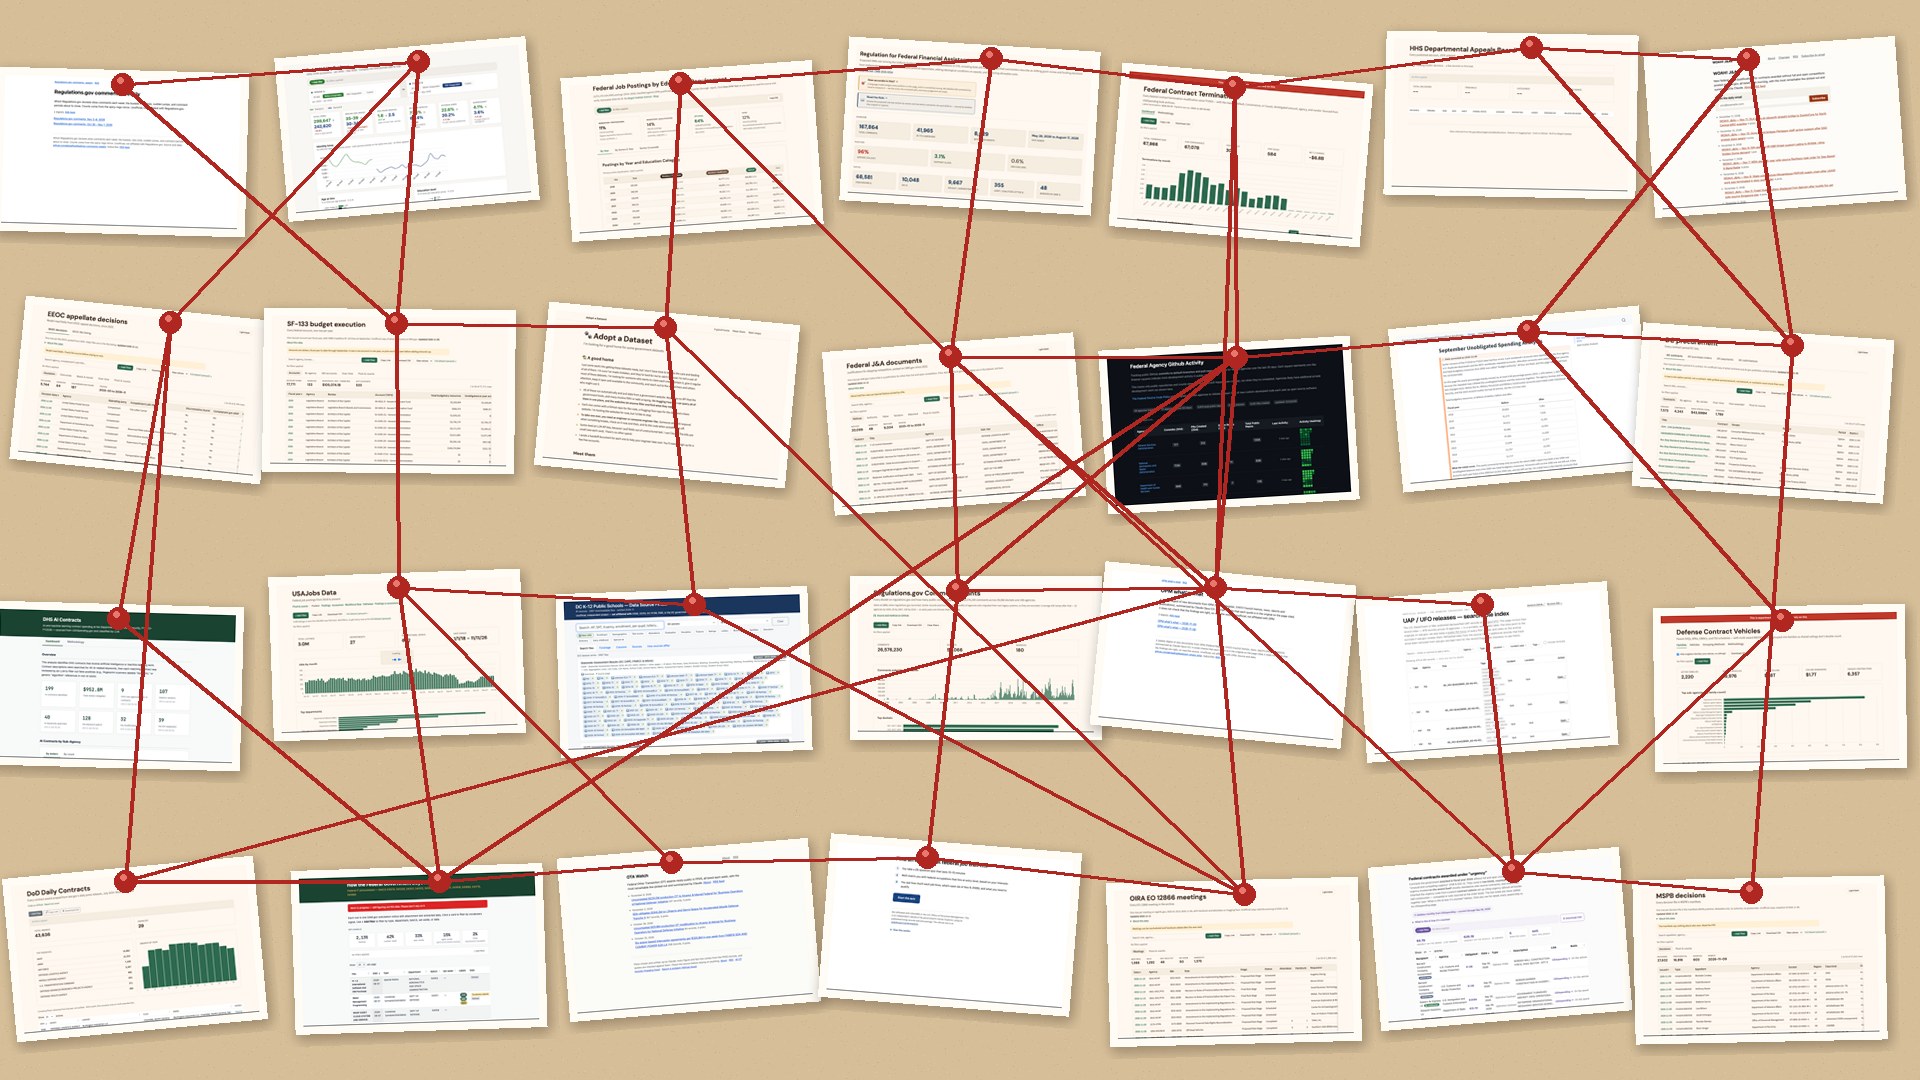
And so on.
I look at a lot of data
My projects all work the same way.
1
Get the data (GitHub actions)
2
Clean it (sometimes LLMs)
3
Lives on Hugging Face
4
Website
Who is commenting on a proposed reg, and are they for it?
167,864 comments. 96% opposed.
How often do federal IT jobs require a degree?
1% of 38,036 postings.
How did ICE surge-hiring attrition compare to previous hiring efforts?
27.5% gone inside a year. CBP lost 10–11%.
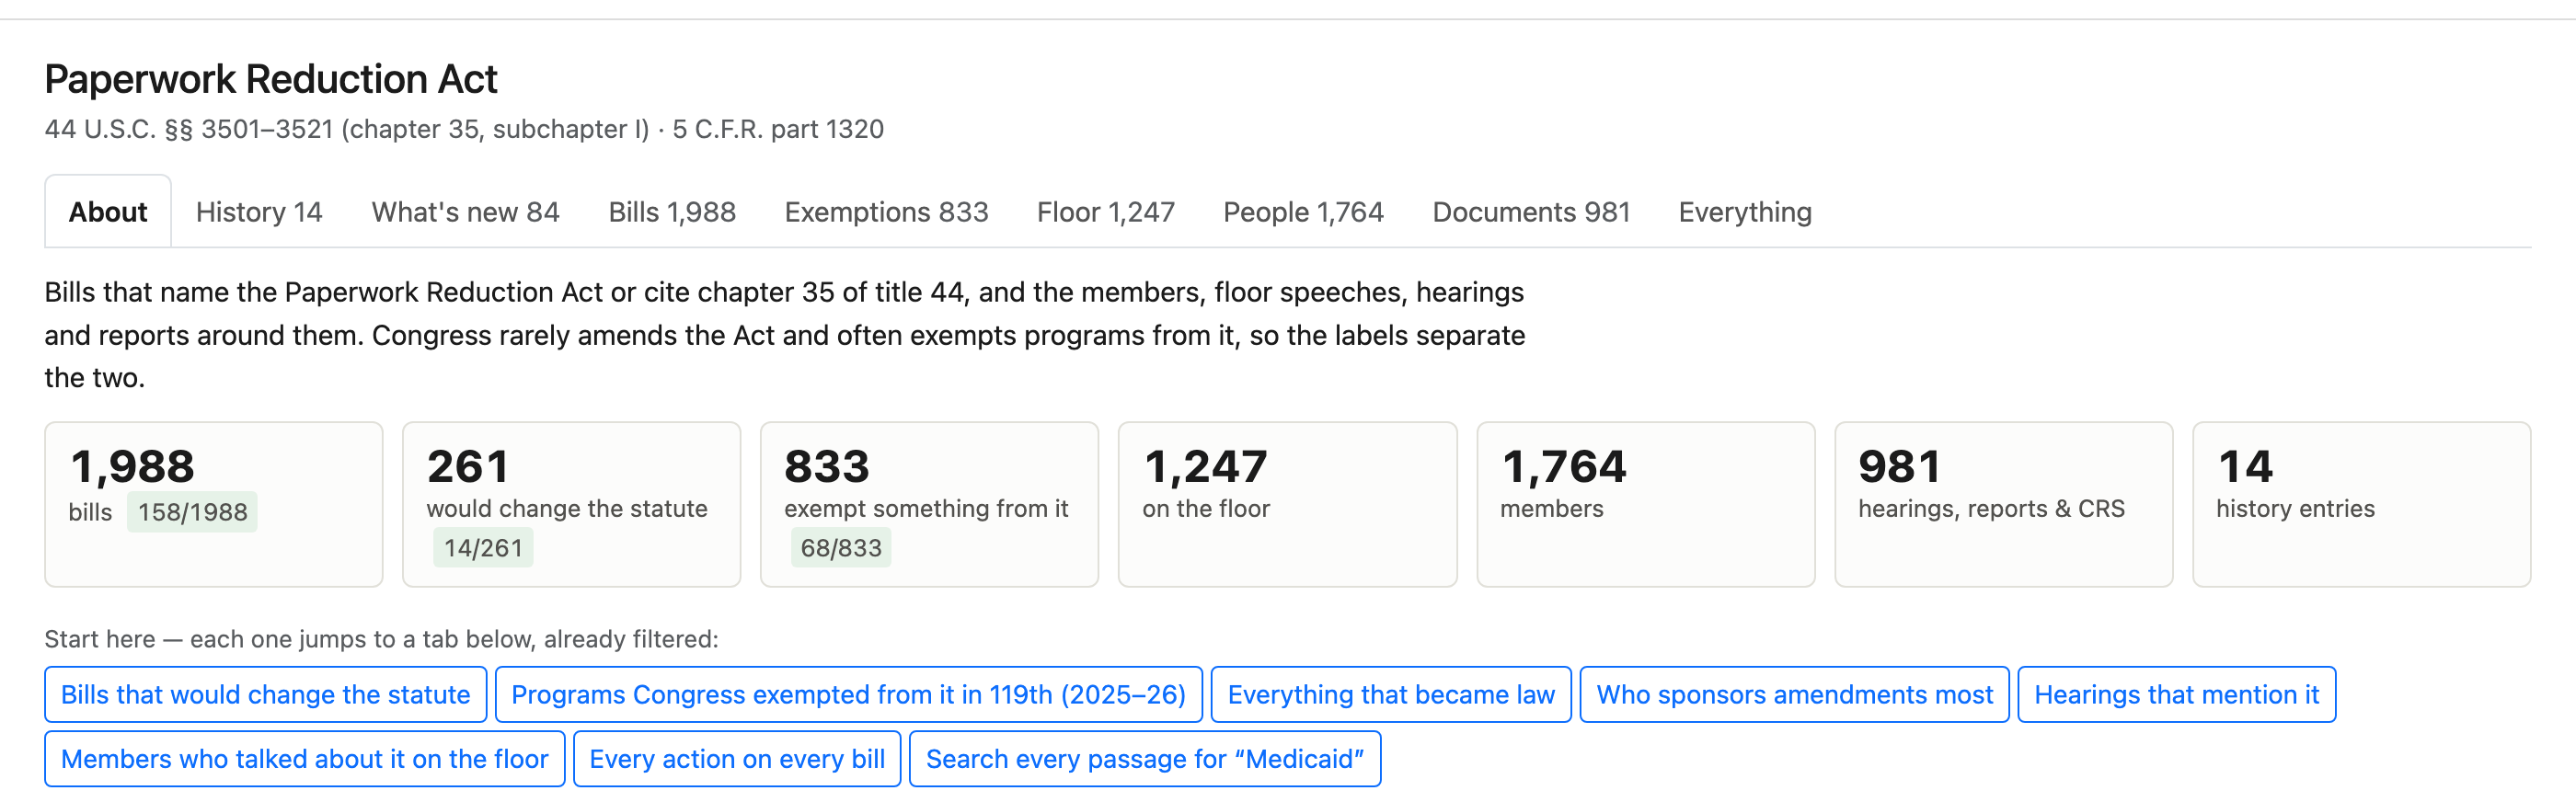
What is Congress trying to do to the Paperwork Reduction Act right now?
12 bills this Congress would amend it. Two passed the House.
A lot of problems are shaped like this
- Job postings (USAJOBS)
- Federal personnel records (OPM)
- Contracts and spending (USAspending)
- Sole-source justifications (SAM.gov)
- Budget execution (SF-133)
- Bills and the Congressional Record
- Public comments (regulations.gov)
- Appeals decisions (EEOC, MSPB, FLRA)
You can do this. Claude can help.
- Answer your own questions
- Build capacity
- Make friends!
Backup · J&A pipeline
What it costs to run
Reading one notice
about $0.004
A day of new notices (about 31)
about $0.13
Writing the daily email
about $0.10 a day
Model calls only. Estimates from the repo’s docs, October 2026.
Backup · J&A pipeline
The regex trick
1
The model gives a quote from the document for each value.
2
A script checks that the quote is really in the document.
3
If the quote isn’t there, the value is thrown out.
Regex cleans up spaces, line breaks and curly quotes first, so a real quote still matches. It also pulls the dollar figure out of the quote to check it against the value.
Backup · Structured output
I define the fields I want with Pydantic. The model has to return exactly those.
class EducationClassification(BaseModel):
category: EducationCategory
reasoning: str
key_quote: str
key_quote: “Must be copied verbatim — do not paraphrase.”
Backup · J&A pipeline
How I check that the fields are good
A random sample of notices, each field compared against the document, using a better model
Field
Right, of 32
Wrong
Signature date
32
0
Estimated value
31
1
Vendor
31
0
Authority cited
30
0